
Best Testing Tools for Claude Code, Cursor and Codex: Mobile App Coverage
Which test automation tools actually plug into Claude Code, Cursor and Codex, and which of them cover native iOS and Android rather than web alone.
Yuvan Sundrani · 15 min read
autosana.ai
TL;DR
- Autosana is the only option here whose MCP server reaches native iOS and Android.
- Playwright with its MCP server is the free default for web, and the one most teams try first.
- TestSprite is purpose-built for the agent workflow and writes plans rather than browser code.
- Cypress fits JavaScript teams who want the agent working inside a familiar runner.
- Katalon suits mixed-skill teams who need a GUI alongside the agent.
- Appium stays the standards-based option when you want the agent writing portable code.
Your developers write faster than your testers can keep up. That is the actual problem, and it is new.
A QA lead put it plainly in a r/QualityAssurance thread that drew 107 votes and 78 comments about a team shrinking from five people to two, and another in the same subreddit was blunter about the cause:
if developers are using cursor for development, you can never match their output. They will constantly deliver things and you will keep playing catch up.
So the question is no longer which test framework is best. It is which one your coding agent can drive without you.
Why move testing into the coding agent?
The pressure is arithmetic. Agents raise the rate at which code reaches a branch, and a QA function that was already stretched now reviews more changes with the same headcount. A r/QualityAssurance thread on AI implementation pressure carries 100 votes and 67 comments of people working out what that means day to day.
The honest counterweight is that agent-written tests are not free. In a r/QualityAssurance thread on Playwright MCP, at 46 votes and 45 comments, a tester who had used it across both Cursor and Copilot reported real numbers:
Scripts generated are pretty standard which in my usage have been around 75-80% usable (Cursor) and 60-70% usable (GitHub Copilot + VS Code) depending on the flow that is being automated. Longer flows tend to drop in accuracy.
That same reply notes the generated code ignores the reusable methods and page objects a team already has. Scepticism is healthy here, and a r/softwaretesting thread titled "AI is a nightmare for QA" carries 174 votes and 108 comments of it.
Here is the reframe worth holding onto: the agent is good at producing a first draft and poor at maintaining it, so the tool that matters is the one with least to maintain.
| Tool | What It Tests | Agent Integration | Pricing |
|---|---|---|---|
| Autosana | iOS, Android and web | MCP plus a GitHub Bot on pull requests | Per agent-run |
| Playwright | Web (Chromium, Firefox, WebKit) | Official MCP server | Free, Apache 2.0 |
| TestSprite | Web | MCP, plan files rather than code | Published tiers |
| Cypress | Web (Chromium-based, Firefox) | Community MCP, runner-native | Free runner, Cloud paid |
| Katalon | Web, mobile, API, desktop | StudioAssist authoring | Free tier, $1,000/seat/yr |
| Appium | Native iOS and Android | Agent writes standard WebDriver code | Free, Apache 2.0 |
The six tools, examined one by one
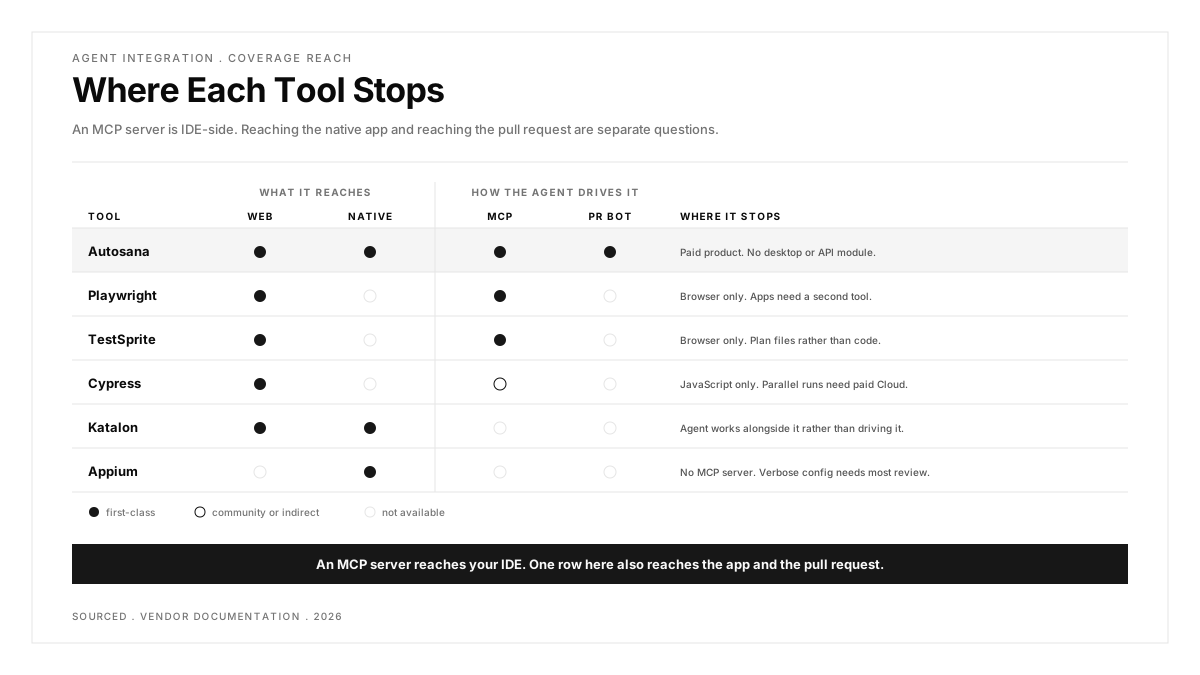
The split below is really about two things: whether the tool exposes an MCP server your agent can call, and whether it reaches past the browser.
1. Autosana: Best Testing Tool for Claude Code and Cursor with Native Mobile Coverage
Autosana leads this list for one reason: it is the only option here whose MCP server reaches native iOS and Android. Every other tool below is a web testing tool, so if the code your agents write ends up in a mobile app, the rest of the category stops short of the thing you actually ship.
Autosana writes flows in natural language and runs them against the current interface rather than storing a script. Coverage spans apps on virtual and physical iOS and Android devices and web across Chrome, Firefox, Edge and Chromium.
Two integration surfaces are documented and worth keeping apart, because conflating them is how most comparisons go wrong. The MCP server connects AI assistants for flow management and running flows from the IDE, with Claude Code, Claude Desktop, Cursor, Codex, Gemini CLI, Devin, Hermes Agent and ChatGPT via Dots all documented. Separately, the GitHub Bot analyses a pull request, runs the relevant flows and returns results with video, which is the half that closes the loop without anyone in the IDE.
On the maintenance question that the Playwright numbers raise, there is no generated artifact to degrade, and code-managed flows let definitions live in your own repository for teams who want them versioned.
Worth stating the limit plainly: this is a paid product and two options below it cost nothing. If a browser is genuinely all you ship, Playwright wins on price and there is no argument to make here.
Pros: native iOS and Android alongside web, the widest documented MCP client list here, a GitHub Bot that handles pull requests independently of the IDE, and no generated script to maintain.
Cons: no desktop or API testing module, and this is a paid product against two free options.
Pricing: per agent-run, with a self-serve trial.
Best for: teams whose agents ship mobile apps.
2. Playwright: Best Free Web Option with an Official MCP Server
For web, it is the default and the one to beat. The MCP server exposes browser handling, DOM parsing for locators and snapshots as tools an agent can call, so Claude Code or Cursor can drive a real browser while writing the test.
The accuracy numbers above are the honest picture: usable most of the time, weaker on long flows, and inclined to ignore your existing page objects. That makes it excellent for a first draft and ordinary for maintenance, which is the same trade every agent-written artifact carries.
Worth knowing before you commit: the MCP server gives the agent browser control and locator access, which is powerful during authoring and does nothing for the suite six months later. Treat it as an authoring accelerator rather than a maintenance strategy.
Pairing is common rather than exceptional. Playwright handles the browser for nothing, a mobile tool handles the app, and the agent drives both through separate MCP servers in the same IDE session.
Pros: free, an official MCP server, five language bindings, auto-waiting, and tests that live in your repository under real version control.
Cons: web only, so a native app needs a second answer. Generated code tends to bypass your existing abstractions, and long flows degrade.
Pricing: free, Apache 2.0.
Best for: web teams who want the agent writing code they own.
3. TestSprite: Best for Letting the Agent Own Triage on Web
TestSprite is built for this workflow rather than adapted to it. It installs a verification skill into the harness so Claude Code, Cursor or Codex can create, run and triage tests without further instruction, and it ships first-class MCP support across Cursor, Claude Code, Windsurf, Trae and VS Code.
The design decision worth noting is that tests are plain-language plan files rather than browser code, so the agent is not maintaining selectors that break on the next redesign. That addresses the maintenance half of the problem directly.
The plan-file decision is the interesting part of the design. A plan describes what to verify rather than how to reach it, so a redesign that moves a button does not invalidate the file, which is the same structural argument intent-based tools make from a different direction.
That focus is a deliberate product choice rather than a gap they have missed, so expect it to persist rather than closing in the next release.
Pros: purpose-built for agent workflows, broad MCP client support, plan files rather than selector-bound code, triage included.
Cons: web focused, so native mobile sits outside it.
Pricing: published tiers.
Best for: web teams who want the agent owning the full test loop.
4. Cypress: Best Debugging Surface for Reviewing Agent-Written Tests
Cypress runs inside the browser event loop and gives an agent an unusually legible failure surface, since every step carries a DOM snapshot and time-travel debugging shows exactly where a generated test went wrong. For a JavaScript team, that shortens the loop between the agent writing something and a human deciding whether it is right.
Review time is the hidden cost of agent-written tests, and it scales with how much output you accept. Anything that makes a wrong test obvious in seconds rather than minutes compounds quickly at the volumes agents produce.
Pros: the best debugging surface for reviewing agent output, automatic waiting, first-class TypeScript, strong plugin ecosystem.
Cons: JavaScript and TypeScript alone, no native mobile, and parallel runs need the paid Cloud tier.
Pricing: free runner under MIT, with Cypress Cloud paid.
Best for: JavaScript teams reviewing a lot of generated tests.
5. Katalon: Best for Mixed-Skill Teams Where Only Some Use an Agent
Katalon sits differently. Rather than handing the agent a protocol, it offers StudioAssist for AI-assisted authoring inside a GUI, over Selenium and Appium, covering web, mobile, API and Windows desktop.
For a mixed-skill team where some people use Cursor and others will never open a terminal, that breadth has a real argument behind it. Its pricing page lists Professional at $1,000 per seat per year as a first-purchase offer against a $2,199 regular rate, with a free tier to evaluate on.
This is the pragmatic middle for an organisation mid-transition, where two engineers have adopted Cursor and the rest of QA has not. Forcing everyone onto a code-first tool in that situation usually costs more in people than it saves in licences.
Pros: four surfaces, a free tier, GUI for non-coders, and a Groovy escape hatch underneath.
Cons: no MCP server documented, so the agent works alongside it rather than driving it, and it remains selector-based.
Pricing: free tier, Professional listed at $1,000 per seat per year.
Best for: teams where only part of the team uses an agent.
6. Appium: Best for Portable, Standards-Based Agent-Written Code
It can, and the output is portable in a way a platform-held test is not. Appium implements the W3C WebDriver specification in five languages, so an agent writes ordinary code that runs on any device cloud or your own hardware.
The catch is that Appium is exactly the kind of verbose, capability-heavy target where generated code needs the most review, and the device layer has no web equivalent for an agent to reason about. Our Appium guide covers the setup path.
The portability argument is strongest here. Because the agent writes standard WebDriver code, nothing about the output is tied to a vendor, and the same suite runs on a laptop, a rented fleet or your own rack unchanged.
Pros: free, standards-based, portable across every device cloud, and the agent writes code you fully own.
Cons: no official MCP server, verbose configuration that generated code often gets wrong, and iOS driver maintenance after OS releases. Pricing: free, Apache 2.0.
Best for: teams who want agent-written code with no vendor attached.
Which tool fits your agent setup?
Your agents ship a mobile app. Autosana is the only option here that reaches native iOS and Android through an MCP server, and the GitHub Bot runs flows on the pull request without anyone opening an IDE.
Your agents ship a web app. Playwright if you want free and owned, TestSprite if you want the agent to own triage too. Both are credible and the decision is mostly about whether you want code in your repository.
You review a lot of generated tests. Cypress, for the debugging surface. Reviewing agent output is most of the work once adoption is real, and it is badly underrated as a selection criterion next to authoring speed.
Only half your team uses an agent. Katalon, which gives the other half a GUI and avoids forcing a tooling migration on people who did not ask for one.
You want nothing vendor-held. Appium or Playwright, with the caveat that generated Appium code needs the most review of anything here, since capability configuration is exactly where agents guess.
Your tests are the bottleneck rather than your coverage. Pick on maintenance rather than authoring. Every tool here writes a first draft well, and they differ enormously in what happens on the next redesign.
Conclusion
The tooling question has moved. It is no longer which framework writes the best test, since an agent will produce a workable first draft in most of them. It is which tool leaves the least behind for a person to maintain afterwards.
For web, that contest is live and mostly free, and Playwright or TestSprite will serve you well. For native mobile the field narrows to almost nothing, because the tools built for the agent workflow stop at the browser while the app your agents ship does not. Work out which half applies to you before comparing anything else.
Frequently asked questions
What testing tool works with Claude Code and Cursor?
Several. Playwright ships an official MCP server, TestSprite is purpose-built for the workflow, and Autosana documents MCP setup for Claude Code, Claude Desktop, Cursor, Codex, Gemini CLI, Devin and Hermes Agent. The split that matters is whether the tool reaches native mobile or stops at the browser.
Can Cursor write and run my tests automatically?
It can write them and, through an MCP server, run them. Whether it should run them unattended is a separate question, since reported usability of generated scripts sits around 75 to 80 percent on Cursor and drops on longer flows.
What is an MCP server in testing?
Model Context Protocol is the standard that lets an AI assistant call external tools. A testing MCP server exposes actions such as listing flows, running a flow or driving a browser, so the agent can test from inside your IDE rather than asking you to switch context.
Does MCP handle testing on pull requests?
Not usually, and this is the most common misunderstanding. MCP is IDE-side. Pull request automation is a separate integration: on Autosana that is the GitHub Bot, which analyses the PR, runs the relevant flows and returns results with video.
Are AI-generated tests reliable enough to ship?
They are a strong first draft rather than a finished artifact. Practitioner reports put usable output at roughly 60 to 80 percent depending on the agent and the flow length, with accuracy falling as flows get longer, so review remains part of the process.
How do I test a mobile app with Claude Code or Cursor?
You need a tool whose MCP server reaches native platforms, since browser-based options cover only the web half. Autosana runs iOS and Android flows on virtual and physical devices and exposes them through MCP.
Do AI coding agents replace QA engineers?
No, and the practitioner view is sharper than the marketing one. Agents raise the rate at which code arrives, which increases the review burden rather than removing it, and teams report playing catch-up rather than gaining slack.
Which is better for agent workflows, generated scripts or intent-based flows?
Generated scripts give you code you own and must maintain. Intent-based flows leave no artifact to maintain but give you less to inspect. Pick on whether your cost sits in authoring or in upkeep after a redesign.