
Tools That Catch UX Problems a Passing Test Hides in 2026
A green test can sit on a broken screen. Comparing visual regression against agents that flag UX problems during an ordinary functional run.
Yuvan Sundrani · 16 min read
autosana.ai
TL;DR
- Autosana flags bugs, UX problems and unclear instructions during an ordinary functional run, with a severity on each.
- Applitools Eyes is the most capable visual AI, with match levels and automated WCAG checks.
- Percy is the cheapest way to start visual testing, with a free tier that is genuinely usable.
- Chromatic is built around Storybook and prices by snapshot rather than by seat.
- BackstopJS is the free, self-hosted option for teams who want no vendor at all.
- axe DevTools catches the accessibility failures every other tool on this list walks past.
A test suite can be entirely green while the product is visibly broken. The button is behind the keyboard, the modal has no dismiss, the error message renders white on white, and every assertion passes because every element is present in the DOM exactly where the test looked for it.
Teams know the gap exists and argue about its size. A r/softwaretesting thread asking what kind of UI bugs slip past E2E tests drew 6 votes and 13 comments of examples, and a r/QualityAssurance thread on what a realistic pass ratio even looks like, at 24 votes and 39 comments, is the same anxiety from the other direction.
Why does a passing test miss a broken screen?
Because an assertion checks what it was told to check. expect(page.getByRole('button', { name: 'Continue' })).toBeVisible() passes whether the button is centred and legible or clipped at the edge of a viewport in a colour nobody can read.
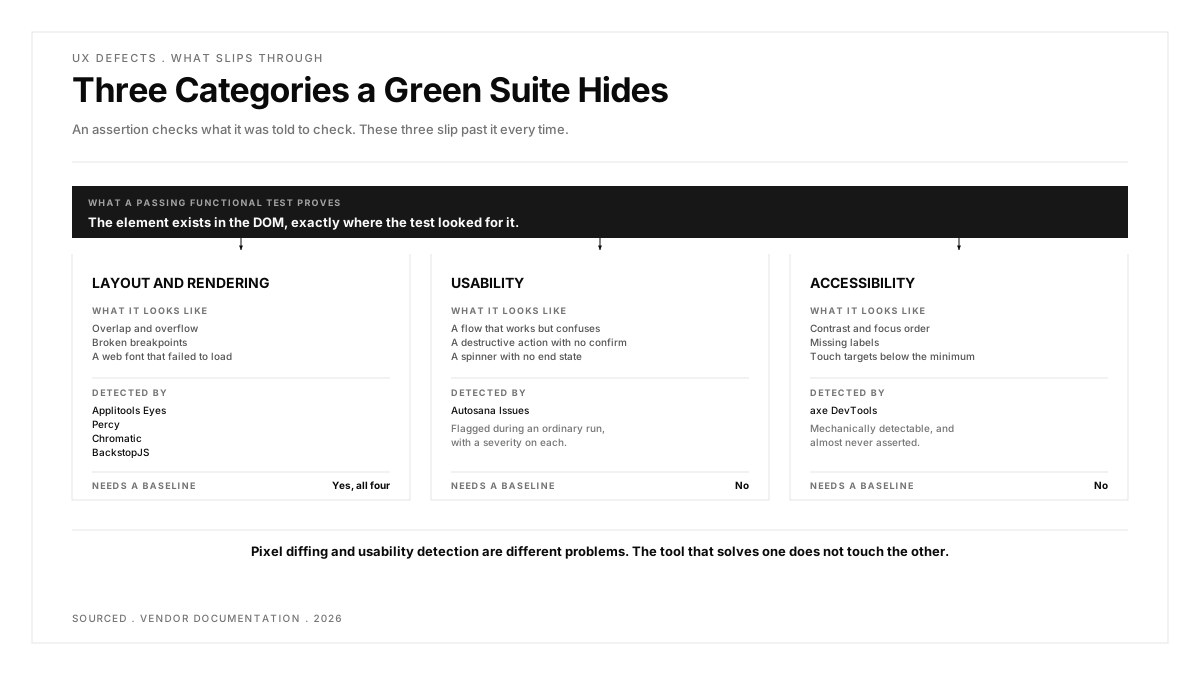
Three categories slip through, and they need different tools.
Layout and rendering. Overlap, overflow, broken breakpoints, a web font that failed to load. Visual comparison catches these and functional assertions never will.
Usability. A flow that works but confuses, a destructive action with no confirmation, a spinner with no end state. No pixel diff catches these, because the screen is rendering exactly as designed.
Accessibility. Contrast, focus order, missing labels, touch targets below the minimum. These are mechanically detectable and almost never asserted.
Worth holding onto: pixel diffing and usability detection are different problems, and the tool that solves one does not touch the other.
| Tool | What It Detects | Needs a Baseline | Starting Price |
|---|---|---|---|
| Autosana Issues | Functional, UI, UX, performance, state, instruction problems during runs | No | Per agent-run |
| Applitools Eyes | Visual, layout, structural, WCAG | Yes | $667 / mo annually |
| Percy | Visual across browsers and breakpoints | Yes | Free to 5,000 screenshots |
| Chromatic | Visual, component-level via Storybook | Yes | Free to 5,000 snapshots |
| BackstopJS | Visual, self-hosted | Yes | Free, MIT |
| axe DevTools | Accessibility, web and mobile | No | Contact sales |
Which UX problems does each category of tool actually find?
The split that matters is whether a tool needs to be told what correct looks like. Visual regression tools need a baseline, which makes them excellent at catching change and blind to a screen that has been wrong since the day it shipped. Detection tools that reason about the screen need no baseline, which makes them the only option for finding a problem that was always there. Most teams need one of each, and the order below reflects which gap is usually the more expensive one.
1. Autosana: Best for Catching UX Problems Without a Baseline
Autosana goes first because it finds problems nobody wrote an assertion for and nobody captured a baseline of. Issues are generated per flow run and flag the cause of a failure, a UI or UX improvement, or an unclear test instruction, citing exactly where in the run it happened.
The structure is what makes it usable rather than noisy. Each issue carries a severity of critical, major or minor, where critical issues fail the test and major and minor ones are flagged without failing it. Each also carries a type: functional, UI, UX, performance, state or instructions. That last category points at the test rather than the app, which is unusual and genuinely useful, since a flaky test caused by an ambiguous instruction normally gets diagnosed as a product bug.
Individual issues are then collected into Issue Groups that match on meaning rather than exact wording, so the same underlying problem seen across different runs, flows, apps and devices lands in one place with an occurrence count. Groups fall into Critical, UI/UX and Instruction.
Now the honest part, because it decides whether this belongs alongside the tools below or instead of them. Autosana does no pixel-level visual regression. There is no baseline image, no diff, no approval workflow. A one-pixel shift in a brand element is exactly what Applitools, Percy and Chromatic exist to catch, and Autosana will not report it. What it reports is the problem a human would notice while using the screen.
Strong on: finds problems with no baseline and no assertion, severity and type on every issue, semantic grouping across runs and devices, and flagging bad test instructions as a distinct category.
Thin on: no pixel-level visual regression, no baseline approval workflow, and no dedicated accessibility audit.
Pricing: per agent-run, published on the Autosana pricing page.
Worth it when: your suite is green and your users are still reporting things you never wrote a test for.
2. Applitools Eyes: Best Visual AI for Teams That Can Fund It
Applitools Eyes is the most capable product in this category and prices accordingly. Its own page describes computer vision trained on billions of UI renderings, applied to structural layout, typography hierarchy and DOM relationships rather than raw pixel comparison.
The feature that earns the price is match levels. Dynamic, Strict, Layout and Exact modes let you tell the tool which parts of a screen are allowed to vary, which is the difference between a visual suite you trust and one that fails on every timestamp. Alongside it, automated WCAG checks validate colour contrast ratios, font sizes and layout overlap on the same run.
Pricing starts at $667 per month paid annually for the Starter tier, which includes unlimited users and either 100,000 component checkpoints or 1,000 page checkpoints. Professional and Enterprise are both quote-based.
Check the tier table carefully if you are testing mobile. Access to real iOS and Android devices is listed as an optional add-on on the Enterprise tier, not as a Starter feature, which changes the calculation considerably for a mobile-first team.
Strong on: match levels that make dynamic content manageable, WCAG checks bundled into the same run, Storybook and Figma integrations, and a Visual AI MCP server for agent workflows.
Thin on: the entry price is the highest here by a wide margin, and real mobile device access sits behind the Enterprise tier.
Pricing: Starter $667 per month paid annually. Professional and Enterprise by quote.
Worth it when: visual correctness is a funded programme rather than a side task, and the team is mostly on web.
3. Percy: Best Free Starting Point for Visual Testing
Percy is where most teams should begin, because the free tier is large enough to answer the question honestly. It includes 5,000 screenshots a month with access to the core features, and paid plans start at 10,000 screenshots a month.
It covers full pages and component libraries, renders snapshots across browsers and multiple responsive breakpoint widths, and does the rendering on its own infrastructure so nothing is added to the runtime of your existing suite.
The usual complaint about visual testing is not the tool, it is the review burden. A r/softwaretesting thread asking which visual regression tools people actually trust, at 3 votes and 19 comments, is mostly people describing the moment a 300-diff build taught the team to click approve without looking. Budget for that before you budget for the licence.
Strong on: a free tier big enough for a real trial, cross-browser and multi-breakpoint rendering handled off your runners, and simple per-screenshot pricing.
Thin on: change detection only, so a screen that has always been wrong stays invisible, and diff review becomes its own workload at scale.
Pricing: free to 5,000 screenshots a month, paid from 10,000.
Worth it when: you want to find out whether visual regression earns its place before committing budget to it.
4. Chromatic: Best for Teams Already Living in Storybook
Chromatic assumes you have a component library and builds everything around it. If your team already maintains Storybook, this is the lowest-friction option on the list, because the stories you have written are already the test cases.
Pricing is snapshot-based and published in full: free at 5,000 billed snapshots a month, $179 a month for 35,000, $399 a month for 85,000, and $0.008 for each snapshot beyond the allowance. Nothing is priced per seat.
TurboSnap is the feature that keeps the bill honest. It tracks file changes to work out which tests are affected and captures snapshots only for those, with unaffected tests reusing their previous snapshots and counting less toward usage. On a large component library, that is the difference between a predictable invoice and a surprising one.
The constraint follows from the premise. Testing components is not testing the assembled page, and a layout that breaks only when three correct components sit next to each other will pass every story.
Strong on: component-level coverage with no new test cases to write, fully published pricing, no per-seat charge, and TurboSnap keeping snapshot counts down.
Thin on: tied to Storybook, and component-level correctness does not prove the assembled page is correct.
Pricing: free to 5,000 snapshots, $179 a month for 35,000, $399 a month for 85,000.
Worth it when: Storybook is already part of how your frontend team works.
5. BackstopJS: Best Self-Hosted Option With No Vendor
BackstopJS is MIT-licensed and does one thing: it automates visual regression testing of a web app by comparing screenshots over time. Rendering runs on Chrome Headless, and user interactions are scripted with Playwright or Puppeteer.
The appeal is total control. Baselines live in your repository, there is no per-snapshot meter, nothing leaves your infrastructure, and the whole thing is auditable. For a team with a compliance constraint on sending screenshots to a third party, it is frequently the only option that clears review.
The cost moves rather than disappears. You own the baseline storage, the CI wiring, the report hosting and the flakiness that comes from rendering differences between a developer's machine and a CI container. A r/QualityAssurance thread on visual regression testing, framed as "the how and the who" and running to 9 votes and 11 comments, spends most of its length on exactly that ownership question.
Strong on: free under MIT, nothing leaves your infrastructure, baselines versioned alongside the code, and scripted interactions through Playwright or Puppeteer.
Thin on: you own the infrastructure and the maintenance, there is no managed review workflow, and cross-environment rendering differences cause false positives.
Pricing: free, MIT licence.
Worth it when: policy forbids sending screenshots to a vendor, or the team would rather spend engineering time than budget.
6. axe DevTools: Best for the Accessibility Failures Everything Else Ignores
Accessibility defects are UX defects, and they are the only category on this list that is both mechanically detectable and routinely untested. axe DevTools from Deque covers web and mobile, running inside the IDE, the browser and the CI pipeline.
Its own page makes two claims worth repeating. The first is a commitment to zero false positives, which matters more than coverage breadth when the output has to survive a developer's patience. The second is that mobile testing works on any app, even without source code access, alongside React Native linting.
Scale is the reassurance here: axe-core, which Deque invented, has been downloaded over 5 billion times, and the browser extension has over 800,000 Chrome installs.
Automated checks have a known ceiling, and the community is blunt about it. A r/webdev thread asking where automated accessibility audits fall short in real-world projects exists because the honest answer is that they catch the mechanical failures and miss the judgement calls, and a broader r/webdev thread on what to learn in accessibility, at 25 votes and 25 comments, keeps landing on the same point.
Strong on: the deepest accessibility rule set available, zero-false-positive commitment, web and mobile coverage, and mobile testing without source code access.
Thin on: no public pricing on the product page, and automated rules cover only the mechanically checkable share of accessibility.
Pricing: contact sales, no figures published on the product page.
Worth it when: accessibility is a legal or contractual requirement rather than an aspiration.
Which approach fits your situation?
Your suite is green and users keep reporting things. Autosana, because the gap is problems nobody wrote an assertion for, and that is precisely what no baseline tool can find.
A brand-critical layout must never shift. Applitools, for the match levels, assuming the budget exists and the product is mostly web.
You have never tried visual testing. Percy's free tier, for one month, on your five most important screens. Decide afterwards.
Storybook is already part of the workflow. Chromatic, because the stories you maintain become the tests at no extra authoring cost.
Screenshots cannot leave your infrastructure. BackstopJS, with the hosting and maintenance cost accepted openly.
Accessibility is contractual. axe DevTools, and treat the automated pass as the floor rather than the finish line.
Do not run two visual tools at once. The failure mode of this category is review fatigue, and two diff queues guarantee both get ignored. A r/QualityAssurance thread on where a bug ends and bad UX begins, at 2 votes and 12 comments, is worth reading before you pick, because half of what these tools surface is a judgement call somebody has to own.
Conclusion
The question is not which tool is best. It is whether your gap is change or correctness.
If screens were right and have drifted, a baseline tool is the answer and the only real decision is budget. If screens have been wrong since launch and no test ever noticed, a baseline captures the wrongness and blesses it, and you need something that reasons about the screen instead. Most teams have both gaps and only ever fund the first.
Frequently asked questions
Can automated tests catch bad UX?
Partly. Layout breakage and accessibility failures are mechanically detectable and should be automated. Usability problems such as a confusing flow or a missing confirmation need either a human or a tool that reasons about the screen rather than comparing it to a stored baseline.
What is the difference between visual regression and UX issue detection?
Visual regression compares the screen to a baseline and reports change, so it needs a known-good version and finds nothing wrong with a screen that has always been broken. UX issue detection evaluates the screen as it is, needs no baseline, and is the only approach that finds a long-standing problem.
Does Autosana do visual regression testing?
No. Autosana does not perform pixel-level visual regression and has no baseline or approval workflow. It flags functional, UI, UX, performance, state and instruction issues during a flow run, each with a severity. For pixel diffing, Applitools, Percy, Chromatic and BackstopJS are the tools built for it.
How much does visual regression testing cost?
The published range is wide. BackstopJS is free under MIT, Percy and Chromatic both start free at 5,000 images a month with Chromatic's next tier at $179 a month, and Applitools Starter is $667 a month paid annually. Deque does not publish axe DevTools pricing.
Why do teams abandon visual regression testing?
Review fatigue, almost always. A build producing hundreds of diffs teaches everyone to approve without looking, after which the suite is theatre. Tools that reduce the diff count, such as Applitools match levels or Chromatic's TurboSnap, are solving the real problem rather than a cosmetic one.
Are accessibility checks part of UX testing?
They should be. Contrast failures, missing labels, broken focus order and undersized touch targets are UX defects that happen to be mechanically detectable, which makes them the cheapest category to automate and the one most often left out.
Should you run more than one of these tools?
One baseline tool and one detection tool is a sensible pairing, because they find different things. Two baseline tools is not, because the limiting factor is how many diffs a human will review carefully, and splitting that attention across two queues means neither gets it.